22B
Fewer wasteful tokens, stale tool results and round trips.
Anyray helps organizations reduce LLM costs with inference compression. Better performance, same quality, lower costs.
Works with models and clouds


Anyray compression engine is grounded in breakthrough research that redefines token compression.
No model in the loop. Same input, same output.
Cached bytes never change.
Any error, the request goes through untouched.
Any step that hurts quality, latency or cache turns itself off.
Anything removed is one call away, byte for byte.
Stable under production load, no loss in quality, and lower spend from day one.
22B
Fewer wasteful tokens, stale tool results and round trips.
28%
Less LLM spend across ScyllaDB's R&D teams and agents.
Putting anything in front of every LLM call takes a leap of faith. Anyray earned that trust. It has cut our spend significantly across R&D and agents. The Anyray team feels like part of our platform team.
Every AI interaction sends wasteful tokens to the model. Every token is billed.
You pay for them in spend and performance, on every call, compounding across sessions and teammates.
Anyray sits between users, agents, and models, optimizing every interaction in real time.
Any provider, any model.


Runs inside your cloud. Nothing leaves your network.
No change to workflow, no IT overhead.
Anyray compresses and optimizes payloads without degrading the output — across every workload, from coding agents to research, analysis, and operations.
By function
38%
Logs, metrics, and JSON dumps.
30%
Code search, file reads, and diffs.
68%
Returns only the output the agent asked for.
79%
Long sessions and cross-session recall.
View and reproduce Anyray benchmarks on GitHub
By workload
| workload | saved |
|---|
| Access logcompacting repetitive entries down to the relevant few | |
| Incident debuggingkeeping only the signals that point to the cause | |
| Synonym-gap logsfinding an OOM event the question never names | |
| GitHub issuesreading GitHub issues/comments to categorize/prioritize | |
| JSON arraykeeping only the fields and items the task uses | |
| Code searchgrep/semantic search returning many file+line hits | |
| Git diff outputreviewing what changed in a commit or PR | |
| Test-suite outputkeeping only the failed tests and the lines that explain them | |
| Flaky-suite re-runcollapsing a near-duplicate test re-run to what changed | |
| Codebase explorationreading source files to understand architecture | |
| Read a Python modulekeeping only the function bodies on the task path | |
| Read a large TS filekeeping only the code paths a TypeScript service task touches | |
| Multi-file tracefollowing one call path across several files | |
| Recurring reportremoving repeated instructions across a nightly batch | |
| RAG retrievalkeeping only the chunks that answer the question | |
| MCP tool bloatkeeping only the tool schemas the task calls |
You finally get the breakdown — spend tied to real work, so you can have an ROI conversation per project, not per invoice.
Anyray deploys inside your environment. Requests are optimized in-network, then forwarded to the model providers you already use.
Runs as a container in your own cloud account. Nothing routed off the network.
Talks only to the model APIs you already trust. No new vendor in the data path.
If Anyray is ever unavailable, traffic routes straight through, untouched.
The Anyray Console gives leaders visibility and governance across AI tools and providers.
Token usage and cost, broken down by user, team, model, and provider.
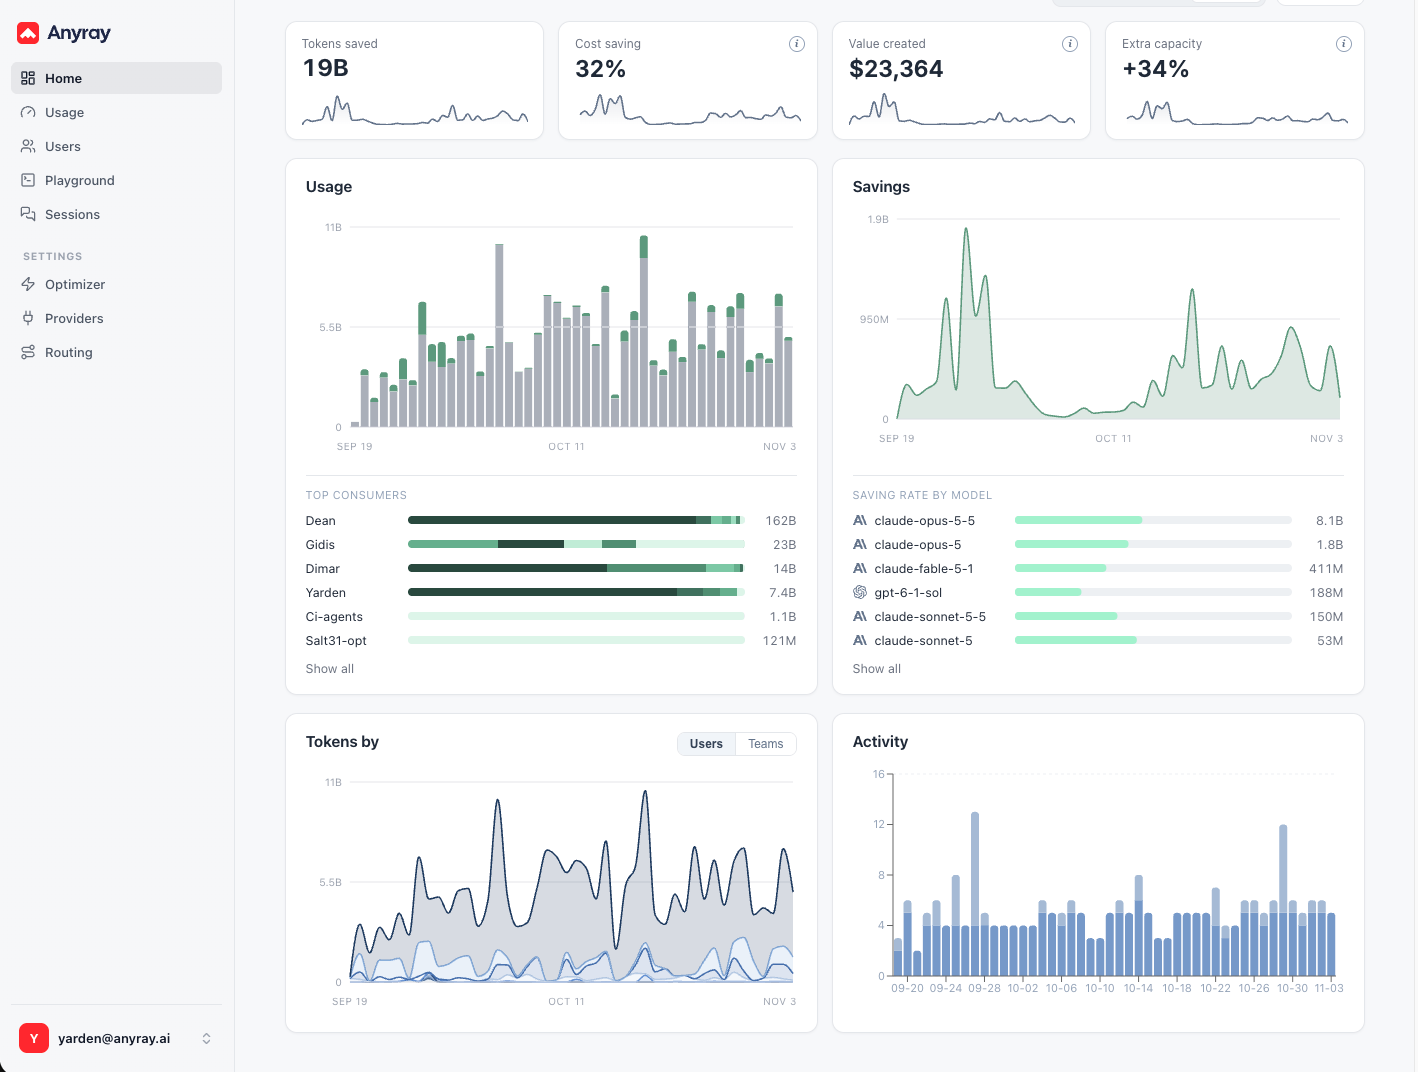
One console for every AI your organization runs.
Resets on the 1st of each month at 00:00 UTC
Budget Window rolling 30d Soft Limit Alert 80% · #ai-platform-opsManage keys, budgets, and fallbacks per user or agent across all tools.
Structural waste is removed automatically before it reaches the model. Every saved token is tracked in the admin console.
Engineers ship more with fewer cycles. Wasted interactions are identified and reduced automatically.
Faster, more accurate responses as context stays clean, with fewer back-and-forth loops.
Token spend by user, team, model, and project, with intent breakdown across debugging, feature development, code review, and more.
No new vendor in the data path. Traffic stays on infrastructure you already trust, with full audit visibility.